Blog-AI
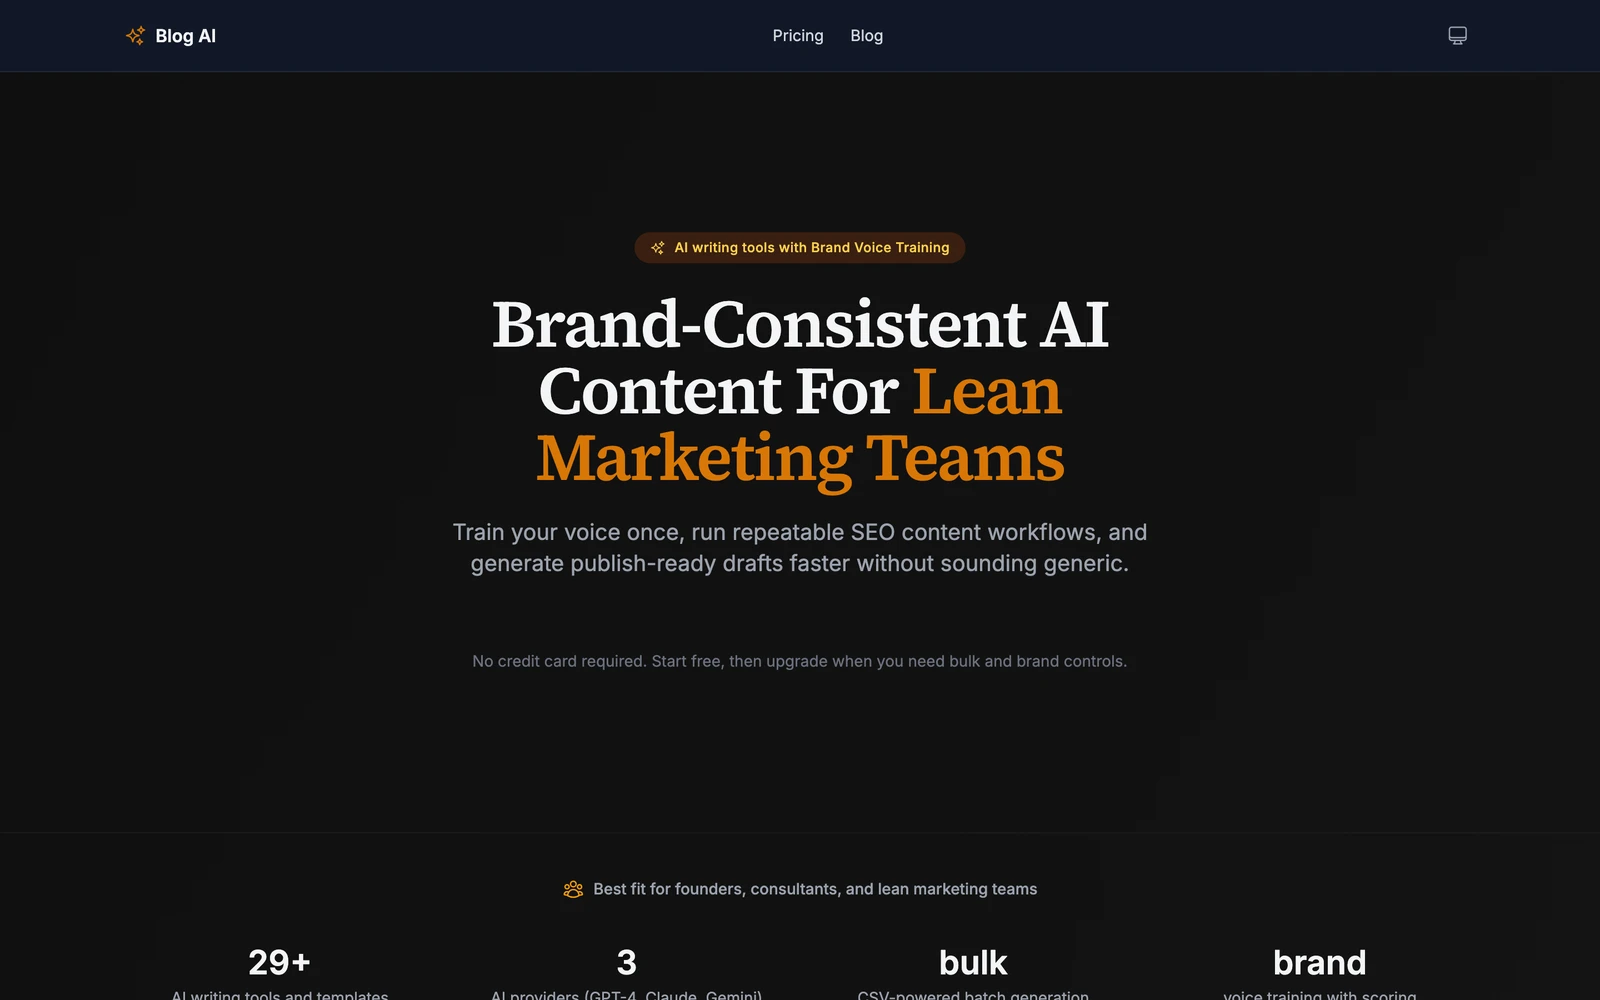
Generates blog posts and books in a trained brand voice: research, outline, per-section drafting, voice scoring, fact-checking and SEO, behind a Next.js front end and a FastAPI service.
The constraint
Generated content is cheap; generated content that sounds like the brand, makes claims it can support, and is structured for search is not. A single prompt produces the first kind.
The approach
Split generation into stages a person can inspect: research, outline, per-section drafting, a brand-voice score, a fact-check pass and SEO. Models sit behind one generate_text() interface, so OpenAI, Anthropic and Gemini are interchangeable per stage.
- 1Stage the pipeline
Broke generation into research, outline, drafting, voice, fact-check and SEO so each step can be inspected and rerun alone.
- 2One model seam
Put every provider behind generate_text() so swapping models is configuration rather than a rewrite.
- 3Score the voice
Added a brand-voice score so 'sounds like us' is a number a draft has to clear.
- 4Check the claims
Added a fact-check stage for claims that need a source.
Outcomes
- Staged pipeline from research to SEO rather than one long prompt
- Brand-voice scoring against a trained voice profile
- Fact-check stage for claims that need support
- Web app, API and a browser extension over the same pipeline
Built a staged long-form generation pipeline (research, outline, per-section drafting, brand-voice scoring, fact-check, SEO) behind a FastAPI service and Next.js front end.
Abstracted OpenAI, Anthropic and Gemini behind a single generation interface, with a browser extension over the same API.
Related projects
- Read
Cocoon
A privacy-first Chrome extension that lowers sensory load online: it softens algorithmic feeds, reduces motion, and keeps a grounding exercise one click away. No accounts, no analytics, nothing leaves the device.
- Read
unlinkd
Get yourself removed from the internet — and keep the proof. A local-first, fully encrypted workspace for data-broker removal requests and the tamper-evident paper trail a GDPR or CCPA escalation actually needs.
- Read
Talker
An open source teaching assistant, built as a USC master's capstone, that drafts answers to course-forum questions from the lecture notes, with hybrid retrieval, a reranker, and an evaluation harness that scores its own retrieval.